GPU inference
Hardware GPUs on the node run quantized and full-weight local models without sending every prompt to a public API.
AI Server Node · physical product
Run large language models on hardware inside your house — not only in someone else’s API region. The MD Vault AI Server Node is a purchased GPU node that sits on your LAN next to the gateway, so prompts and context stay under your roof with your personal data.
Local inference List $3,499 · Data + AI Stack $4,799
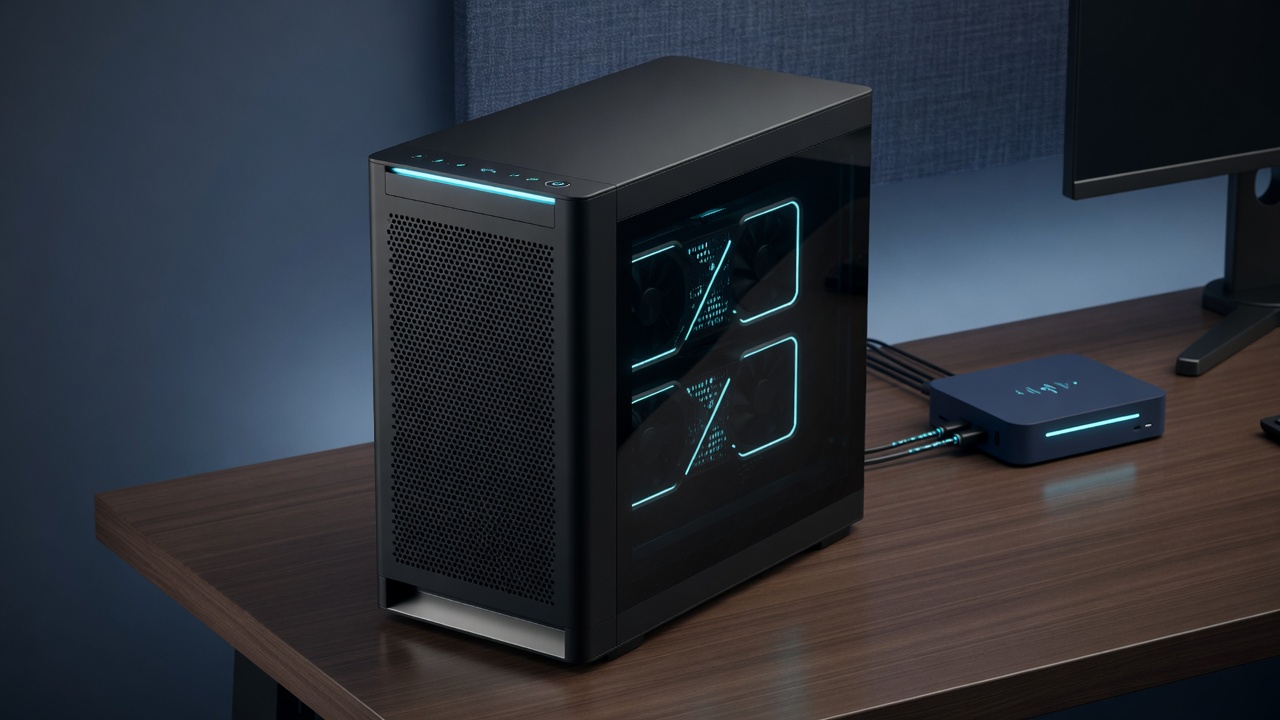
The gateway remains the data-home edge (files, photos, contacts, DHCP, Wi‑Fi). The AI node is the inference box. Buy either alone or the Data + AI Stack bundle.
Hardware GPUs on the node run quantized and full-weight local models without sending every prompt to a public API.
Talks to phones, PCs, and MD Hub agents over house Wi‑Fi and Ethernet — behind your gateway edge.
Docker path for model runtimes and approved AI services, restartable on your metal.
When paired with the gateway, Guard can see node health and network paths the same way it watches other vault servers.
| Class | On this node (typical) |
|---|---|
| Coding / agent work | 14B–32B class coder and general models at Q4-class quant on ~24 GB VRAM path |
| Chat & reasoning | Household assistants, summarization, and private document Q&A against vault libraries |
| Embeddings | Local embedding models for search over files and notes you brought home |
| Out of band | 70B+ full Q4 without multi-GPU or heavy offload — ask Contact for multi-GPU quotes |
AI Server Node
$3,499
Single GPU-class node for local LLMs. Physical product — not a cloud seat.
Data + AI Stack
$4,799
Gateway + AI Server Node. Data home and private inference together.
Gateway alone
$1,499
Start with data home and network; add the AI node when you want local models.
List prices are USD MSRP for physical goods. GPU SKU generation and VRAM class ship with the order confirmation. Multi-GPU / enterprise nodes quote on Contact.